
Agno's AIMLAPITools puts each media capability behind its own enable_* flag and its own model setting, so an agent gets only the tools you pick. Out of the box it uses openai/gpt-image-2 for images, bytedance/seedance-2-5 for video, openai/tts-1 for speech and deepgram/nova-3 for transcription, and every model can be swapped for another one on the gateway.
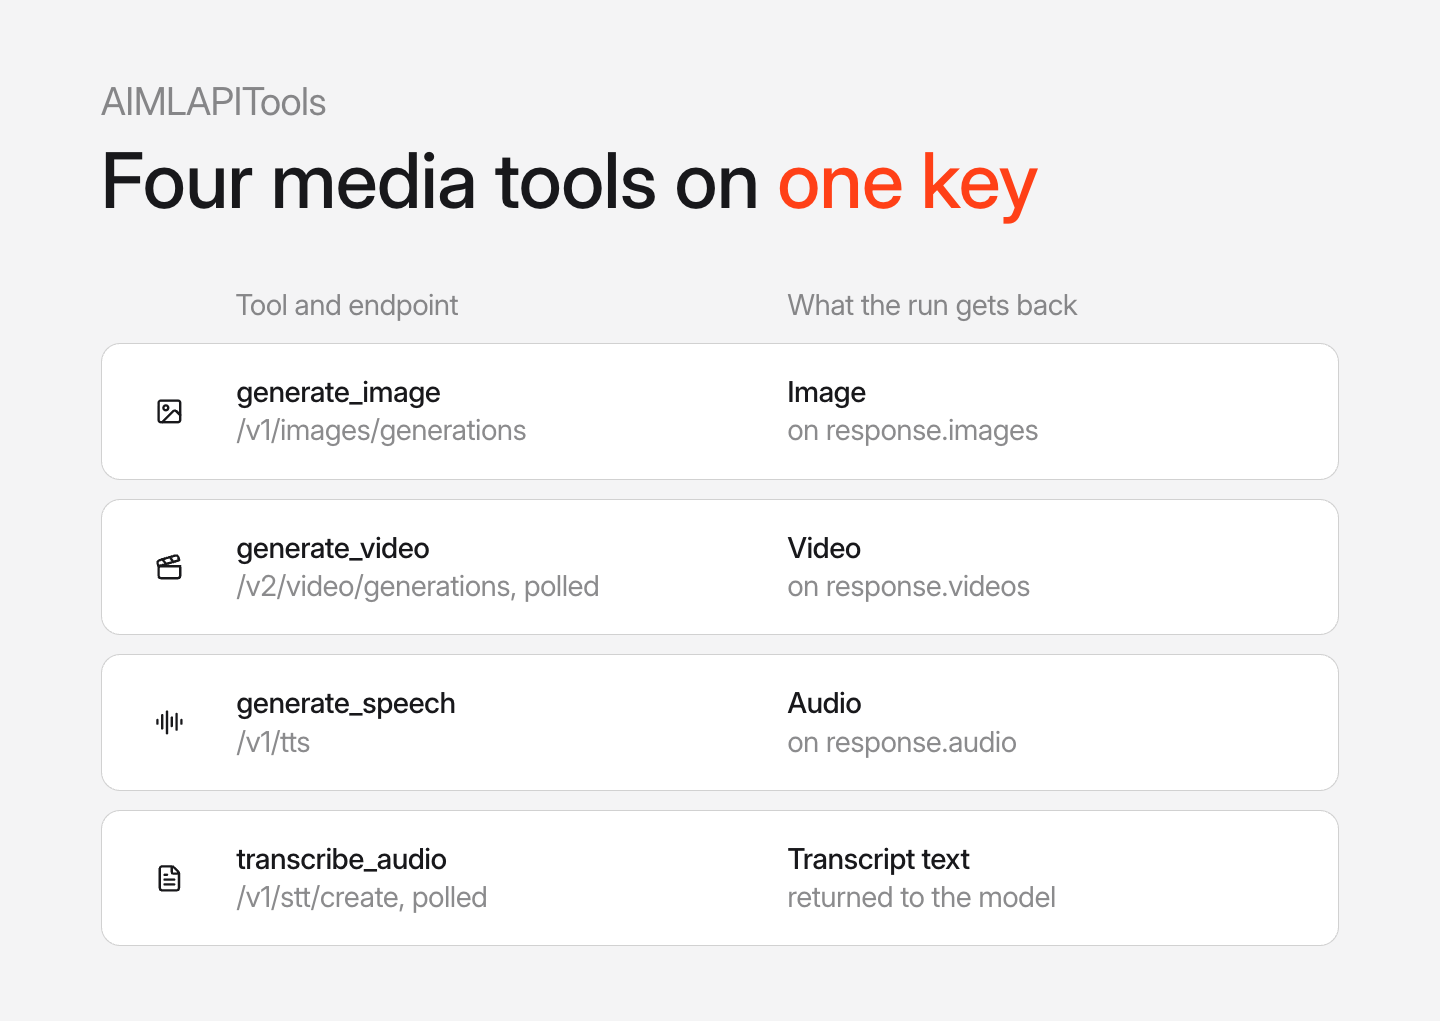
The toolkit reads the same AIMLAPI_API_KEY as the AIMLAPI chat model, so one key runs both:
from agno.agent import Agent
from agno.models.aimlapi import AIMLAPI
from agno.tools.models.aimlapi import AIMLAPITools

tools = AIMLAPITools(enable_generate_video=False, base_dir="tmp")
print([tool.__name__ for tool in tools.tools])
# ['generate_image', 'generate_speech', 'transcribe_audio']

agent = Agent(
    model=AIMLAPI(id="gpt-5.6-luna"),
    tools=[tools],
    send_media_to_model=False,
)

response = agent.run("Generate an image of a lighthouse in a storm")
for image in response.images or []:
    print(image.mime_type, len(image.content))
The image, video and speech tools download the finished file and return a ToolResult with an Agno Image, Video or Audio holding the bytes, the MIME type and, for images and video, the original prompt. transcribe_audio hands the transcript straight back to the model as text.
Video and transcription run as jobs on AI/ML API's side. The toolkit submits the job and polls it, every 5 seconds for up to 900 for video and every 2 seconds for up to 300 for a transcript, and it retries a transient poll failure up to three times so a network blip doesn't abandon a job that is still billing. Async agents get the same tools as coroutines under arun.
transcribe_audio takes an https URL or a path inside base_dir, and with restrict_to_base_dir=True it refuses anything outside that folder, which keeps a prompt from making the agent upload an arbitrary file. Asset downloads never carry your API key.
See the cookbook, and learn more about AI/ML API in the documentation.
Frequently asked questions
Add AIMLAPITools() from agno.tools.models.aimlapi to the agent's tools and set AIMLAPI_API_KEY. Every tool is on by default; pass enable_generate_video=False or any other enable_* flag to leave one out.
The image, video and speech tools return a ToolResult carrying Agno Image, Video or Audio objects with the file bytes, and Agno places them on the run output as response.images, response.videos and response.audio.
Yes. transcribe_audio uploads a file from the toolkit's base_dir, which defaults to the working directory, or sends an https URL. With restrict_to_base_dir=True, the default, it refuses any path that resolves outside that folder.
No. Every tool has an async variant that Agno uses under arun, so polling a video or transcription job waits on the event loop without blocking it.
Shipped around the same time
October 1, 2026
Changelog
v3.1.0GPT-6 models now count as native reasoning models
Ray, Yash Pratap Solanky
1 min read
October 1, 2026
Changelog
v3.1.0A paused run continued in the background no longer repeats its tool call
Kaustubh Shukla, Harsh Sinha, and 1 other
1 min read
October 1, 2026
Changelog
v3.1.0OpenAIResponses recovers when the chained response is gone
Yash Pratap Solanky, Harsh Sinha
1 min read